
Detection & evals
CMMLU
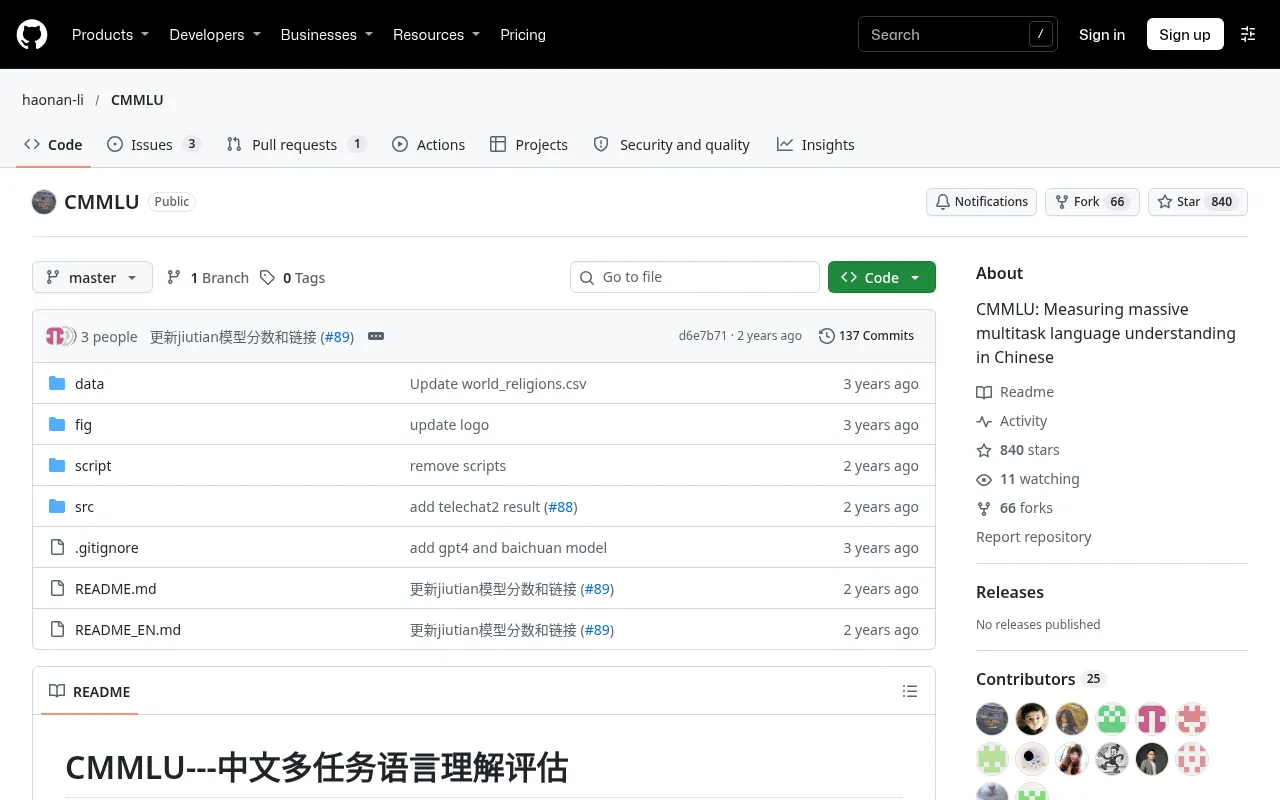
CMMLU is a comprehensive evaluation benchmark specifically designed to assess the knowledge and reasoning capabilities of large language models within the Chinese context.
What is CMMLU?
CMMLU is a comprehensive evaluation benchmark specifically designed to assess the knowledge and reasoning capabilities of large language models within the Chinese context.Developed by researchers including haonan-li, it addresses the gap in existing tools by providing a localized perspective on model performance.
Unlike generic benchmarks, CMMLU covers 67 topics ranging from basic subjects to advanced professional levels.These include natural sciences requiring calculation and reasoning, humanities and social sciences dependent on deep knowledge, and Chinese-specific common sense such as local driving rules.Many tasks feature answers specific to China, making it a fully localized testing standard.
The project open-sources datasets, evaluation scripts, and detailed leaderboards, supporting various testing modes like zero-shot and five-shot.Researchers and developers can access the data via the GitHub repository to verify model instruction-following abilities and check for data contamination, ensuring a more accurate assessment of real-world applicability in Chinese environments.
Key features
- Comprehensive ToCovers 67 topics spanning STEM, humanities, social sciences, and more, thoroughly examining model knowledge breadth.
- Highly LocalizedIncludes tasks with China-specific answers, such as local driving rules and cultural common sense, avoiding Western-centric biases.
- Multi-Level DiffQuestions range from basic subject knowledge to advanced professional reasoning, effectively differentiating model capability levels.
- Multiple TestingSupports zero-shot and five-shot evaluation settings, offering flexible solutions for model performance testing.
- Strict Data ValiVerifies instruction-following abilities and checks for data contamination in non-public API models to ensure leaderboard authenticity.
- Open Source & TrAll data, scripts, and evaluation code are publicly available on GitHub, facilitating community reproduction and further development.
How to use it
- Visit the official CMMLU GitHub repository page.
- Read the README file to understand the benchmark's detailed structure and topic categories.
- Download the evaluation data from the dataset folder.
- Run the evaluation scripts using the code provided in the src or script directories.
- Compare your model's scores in zero-shot or five-shot modes with the official leaderboard.
- For Classical Chinese evaluation, refer to the ACLUE benchmark mentioned in the project.
Where it fits
- Model DevelopmenAI R&D teams use CMMLU to quantify improvements in knowledge understanding and reasoning capabilities of new models in Chinese contexts.
- Academic BenchmaResearchers utilize this benchmark to analyze performance differences among various model architectures when handling China-specific tasks.
- Industry Model SEnterprises consult the leaderboard to select models that excel in humanities, social sciences, or local common sense for specific business applications.
Pricing and free quota
CMMLU is an open-source project with freely accessible datasets and code.Pricing follows the official site.
Who it is for
- Large Language Model Researchers
- AI Algorithm Engineers
- NLP Scholars
- Chinese AI Application Developers
FAQ
What capabilities does CMMLU primarily evaluate?
It primarily assesses knowledge and reasoning capabilities of language models in Chinese contexts, covering natural sciences, humanities, social sciences, and China-specific common sense.
How is the authenticity of listed models ensured?
For non-public API models, the team verifies basic instruction-following abilities and checks for data contamination before updating the leaderboard.
What if I need to evaluate Classical Chinese proficiency?
CMMLU focuses on modern Chinese.For Classical Chinese evaluation needs, the official recommendation is to use the ACLUE benchmark.
Which testing modes are supported?
The official leaderboard displays model performance in five-shot and zero-shot tests, but users can configure other modes as needed.